Right now, the technology sector is experiencing a massive identity crisis.
Ever since ChatGPT cracked open the cultural zeitgeist in late 2022, job titles have been scrambled like eggs. Software developers who write two prompt templates on a Friday afternoon are updating their LinkedIn headlines to "Senior AI Engineer" on Monday morning. Meanwhile, traditional Data Scientists and Machine Learning Researchers are frustratedly asking: "Wait, isn't this just what we've been doing for the last fifteen years?"
The answer is an emphatic no.
Over the next 12 weeks, I am diving deep into the foundations of AI Engineering—reading through four foundational engineering texts cover to cover (Chip Huyen, Andrew McMahon, Alex Xu, and AWS Data Engineering). And Chapter 1 of each of these books makes one thing crystal clear: Data Engineering, ML Engineering, and AI Engineering are three fundamentally distinct disciplines.
Imagine you're building the world's most epic Lego Amusement Park:
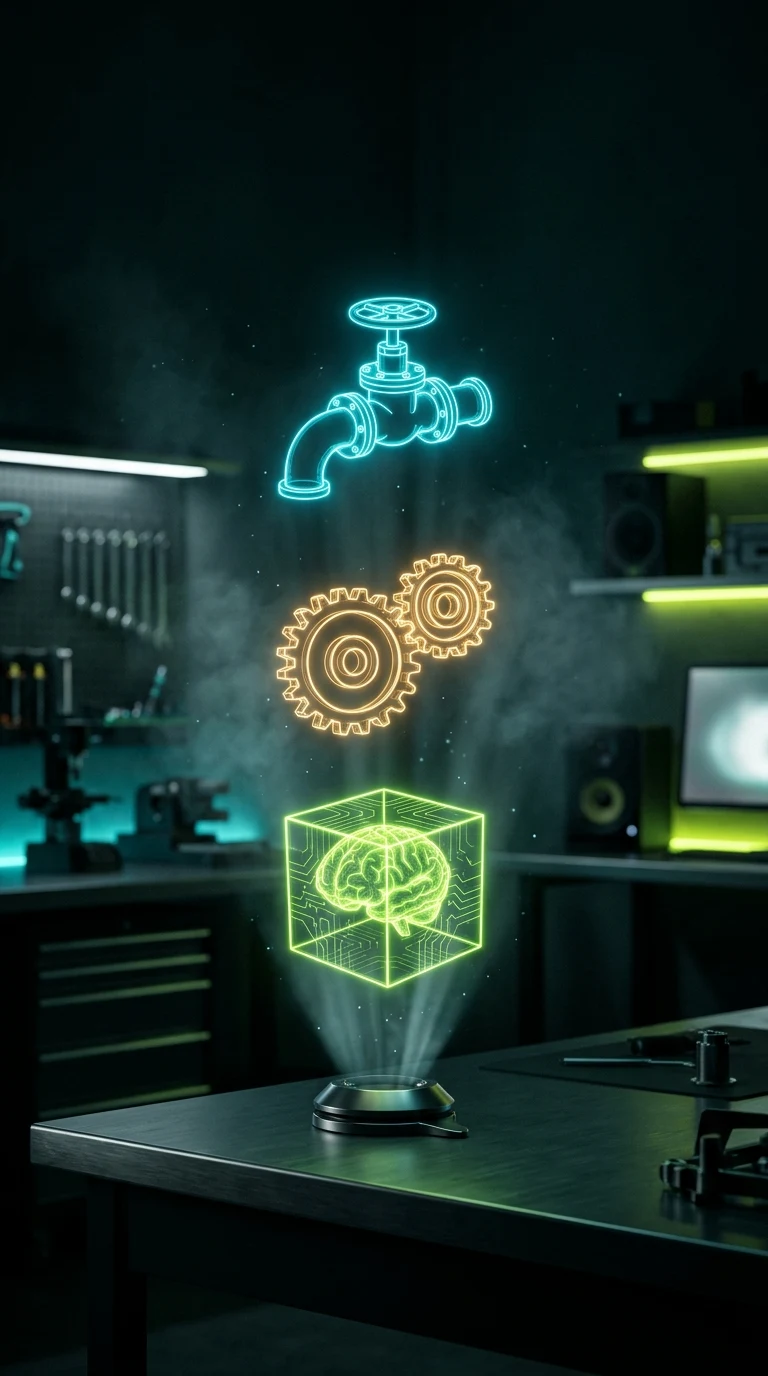
1. The Data Engineer is the civil construction crew. They clear the bedrock, pour the concrete roads, lay down the electrical grid, and plumb the high-pressure water pipes. If they fail, the park floods with dirty sewage and none of the rides get electricity.
2. The Machine Learning Engineer is the mechanical engineer. They sit in a workshop with grease on their overalls, designing custom roller-coaster engines from raw steel and ball bearings. They tune the gears, optimize the motor torque, and calculate the physics of the loop-de-loops.
3. The AI Engineer is the park director. They don't build roller-coaster motors from scratch. Instead, a company in Japan delivers giant, pre-built, hyper-intelligent talking robot dinosaurs (Foundation Models). The AI Engineer's job is to wire those robot brains into the park's computer system, write safety protocols so they don't scare children, equip them with park maps (RAG), and coordinate which ride they should guide visitors to next!
The 3 Disciplines: Side-by-Side Taxonomy
- Core Mission: High-throughput, reliable movement of raw bits.
- Primary Tools: S3, Apache Spark, Kafka, AWS Glue, dbt, Snowflake.
- Success Metric: Data freshness, zero data loss (99.999% durability), pipeline latency.
- Mental Model: Plumbing, reservoirs, and electrical grids.
- Core Mission: Training custom neural networks from raw math.
- Primary Tools: PyTorch, TensorFlow, MLflow, Ray, Feature Stores, CUDA.
- Success Metric: Loss function convergence, F1-score, inference latency (<20ms).
- Mental Model: Physics, linear algebra, and gradient descent.
- Core Mission: Orchestrating pre-trained foundation models into resilient systems.
- Primary Tools: LangChain, LlamaIndex, vLLM, Vector DBs, Pydantic, Evals.
- Success Metric: Task completion accuracy, hallucination rate, token cost, TTFT.
- Mental Model: Cognitive psychology, compilers, and distributed systems.
The Paradigm Shift: From Deterministic Code to Probabilistic Cores
As Chip Huyen points out in Chapter 1 of AI Engineering, the fundamental difference between classic software engineering and AI engineering comes down to one word: determinism.
In traditional computer science:
Input X + Algorithm Y === Output Z (100% of the time, in 5 milliseconds)
In AI Engineering:
Natural Language Prompt + 70B Foundation Model === Probabilistic Distribution of Tokens (Takes 1,500ms)
Your core computing engine is no longer a microchip executing strict binary instructions. It is a probabilistic token predictor. It can write poetry, debug SQL, or summarize an SEC filing—but it can also hallucinate a non-existent tax law or fail to adhere to JSON schemas.
The job of the AI Engineer is not to become a poet whispering magic words into a prompt box. The job of the AI Engineer is to build hard, deterministic software scaffolding around that probabilistic brain:
- Context Construction (RAG): Retrieving the exact 3 chunks of ground-truth data from the Data Engineer's S3 lake before the prompt is synthesized.
- Structured Output Enforcement: Forcing the model's output through Pydantic schemas and grammar-constrained decoding (e.g. Outlines, Instructor) so downstream microservices never crash.
- Evaluation Harnesses: Running automated golden-dataset evals on every commit to measure if a prompt tweak improved accuracy or broke edge cases.
- Cost & Latency Budgets: Routing queries dynamically between small fast models (Gemini Flash, Claude Haiku) and large reasoning models (o1, Sonnet 3.5) to keep unit economics viable.
Why 90% of Companies Need AI Engineers, Not ML Engineers
Unless you are OpenAI, Anthropic, Google DeepMind, or Meta, your company is almost certainly not going to train a frontier foundation model from scratch. Spending $20 million on GPU clusters to recreate what already exists via an API or open-weights model is economic suicide.
What companies actually need are engineers who understand how to take existing, state-of-the-art cognitive engines and plug them safely into enterprise databases, customer interfaces, and background automations.
That is the craft of the AI Engineer. And that is what we are building together over the next 12 weeks.